“We find that indiscriminate use of model-generated content in training causes irreversible defects in the resulting models, in which tails of the original content distribution disappear.”
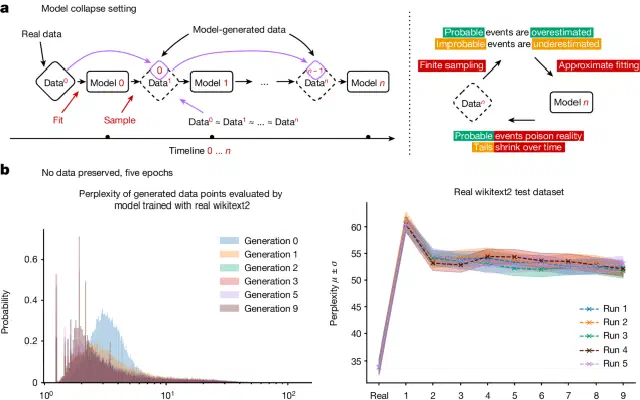
The team fine-tuned OPT-125m on its own output, generation after generation. With none of the original data kept, perplexity on the real task went from 20 to 28, and the improbable stuff vanished first. Keeping 10 percent of the human data held the damage to minor. The paper’s own conclusion is that genuine human data keeps getting more valuable, which is bad news for every lab scraping a web it is busy filling with model output.